Before AI, Get the Entity Right
Why resolving fragmented identities and relationships is essential for reliable AI, analytics, and decision-making.
Before AI, Get the Entity Right
Why resolving fragmented identities and relationships is essential for reliable AI, analytics, and decision-making.


Key takeaways
 Before an organization can trust an AI model, a dashboard, or an automated decision, it has to trust its understanding of the people, businesses, and assets behind its data.
- AI reasons over whatever entities its data presents, so three unresolved records for one customer become three customers and lead to a plausible but wrong answer.
- Once organizations trust their entities, graph analytics can reveal hidden connections across ownership chains, corporate groups, and fraud networks that single records miss.
Organizations are racing to operationalize AI, rolling out new copilots, agents, predictive models, and analytical workflows that promise faster insights and better decisions across every industry. However, most initiatives still won't deliver consistent business value.
This is because for many decision-based use cases, before an organization can trust an AI model, an analytical dashboard, or an automated decision, it must first trust its understanding of the people, organizations, assets, and locations that the decision depends upon.
In other words: before analytics and before AI, get the Entity right.
The identity challenge and opportunity underpinning enterprise data
A record is what a system stores about someone; an Entity is the actual person, business, or asset behind it. In real life, this shows up as a customer appearing in a CRM platform, a billing system, an onboarding application, and a support database. A business could exist across multiple legal entities, historical names, and acquired subsidiaries. An individual might appear with different addresses, surnames, identifiers, or data-entry variations.
Each record may be correct in isolation, but when the Entity on which the record is based is isolated across multiple systems, the records offer only a fragmented view of reality. This is why Entity Resolution is essential.
Entity Resolution is the discipline of determining which records refer to the same real-world Entity and, equally importantly, which do not. Resolving these records is a hard challenge in enterprise data.
Why AI amplifies the problem
The quality of an AI system depends on the quality of the information it receives. If the underlying data presents three different versions of the same customer, the model reasons over three customers instead of one. If ten companies are part of the same corporate group but appear separately, the model reasons over ten independent organizations rather than the complete group. Without resolving the Entity for the use case at hand, the model may reason over a plausible Entity at best and an incorrect one at worse, but it will almost certainly miss the most meaningful accurate representation.
With plausible inputs, a model can be technically accurate and still land on the wrong answer. AI compounds that risk, training, inferring and acting on imperfect data across the pipeline when unchecked. With meaningful inputs, a model can be technically correct and deliver a differentiated, real-world answer.
The challenge is bigger than duplicate or fragmented data
Duplicate and fragmented records are one symptom of a bigger problem: real-world data is naturally messy, always changing, and never static.
People change names, companies merge, contact information evolves, and data entry itself varies between systems, often following different naming conventions from country to country. Some records contain limited information, others contain mistakes, and complexity is natural because we can present identity differently. For example, my being known as Dad to my children, Rob to my team, or ‘Bobby Francais’ to Vish, my CEO.
More seriously, fraudsters, money launderers, and other bad actors actively try to obscure their identities by manipulating data and creating additional layers of ambiguity that, say, criminal or financial investigation teams must overcome.
Factor in these bad actors and poor data entry, Entity Resolution is rarely fixed and solved in one instance. It is an ongoing job to understand what the data represents and how closely it reflects the real world. This is a key purpose of the Quantexa Platform and its Entity Resolution capabilities.
What is Entity Resolution?
How does Entity Resolution work?
Imagine a bank has three customer records:
John Smith.
John Citizen.
J. Citizen.

They sit in different systems, one in wealth management, another, the current account, in the central database, and the third for brokerage. They can look like three people when they might be one or two. At Quantexa, our Decision Intelligence Platform brings the data together, including useful outside data such as company records or watchlists. It then compares key details such as names, addresses, phone numbers, accounts, and company links to layer identity around the entities.
Quantexa does not make a match from one detail alone. Quantexa compares attributes across records to assess whether they represent the same real-world entity. It combines matching rules, similarity scoring and relationship analysis to resolve duplicates and uncover hidden connections. If, then, the data shows that John Citizen and J. Citizen are the same person, their records can form one clear entity.
John Smith, on the other hand, could be someone else but share an address, account, or company link with John Citizen. In that case, Quantexa keeps them as two people and shows the link between them.
This is Entity Resolution in action, and it turns records held across many systems into a clearer view of who each person or company is, where the data came from, and how they may be connected.
Linking too much and linking too little
Entity Resolution must balance competing risks to provide a contextually meaningful answer. On one side is the risk of over-linking, where records belonging to different Entities are incorrectly merged together. On the other side is under-linking, where records that describe the same Entity remain disconnected.
The ideal balance depends on the business objective. Fraud and investigative use cases often favour higher recall, accepting some over-linking (false positives) to reduce the risk of under-linking (false negatives) and missing a critical connection.
Customer-management and regulatory use cases typically favour higher precision, where over-linking unrelated individuals could create significant operational or compliance risks.
A fraud team investigating a case and a compliance team running regulatory checks want different things from the same technology, which is why Entity Resolution needs to be guided by the business context which it, in turn, informs.
More than statistics alone
Even with many metrics, reports, and statistical indicators available to assist Entity Resolution, statistics alone rarely tell the full story.
As I always emphasize: understanding the business context surrounding the data often distinguishes successful implementations from less successful ones. A large number of highly connected entities, for example, might indicate a matching failure. Alternatively, it may simply reflect the reality of a trading book, where entities are naturally highly connected.
In other words, organizations achieve the best outcomes when technical indicators are combined with domain expertise, investigator and analyst feedback, and operational understanding.
Beyond the Entity. The power of graph technology and seeing relationships
Once organizations trust their entities, graph and network analytics is where the trust starts to pay off: customers connect to accounts, accounts to transactions, businesses to subsidiaries, suppliers to products, and people to organizations, locations, devices, and events.
These relationships often reveal insights that individual records cannot. A sanctions investigation might uncover hidden exposure through a chain of ownership; a customer intelligence initiative might surface opportunities inside a corporate group; a fraud investigation might expose connections that get hidden in a traditional tabular view of data.
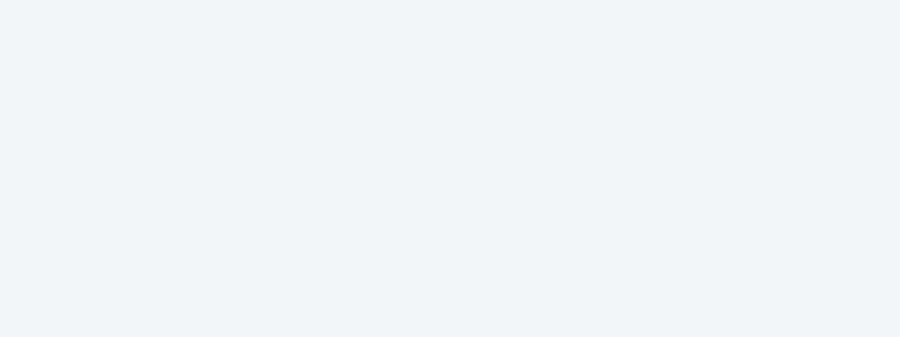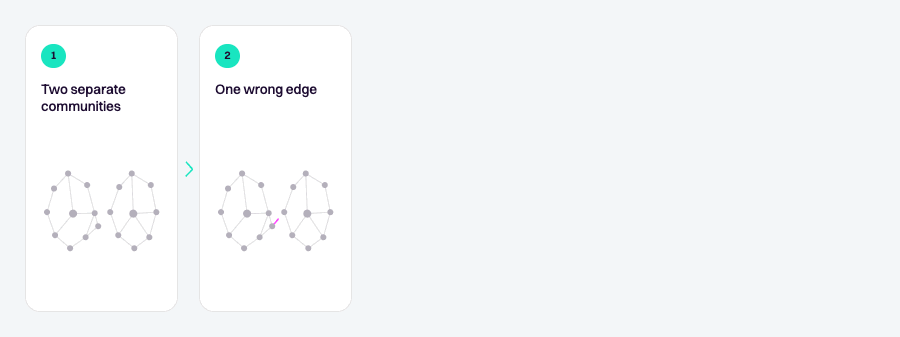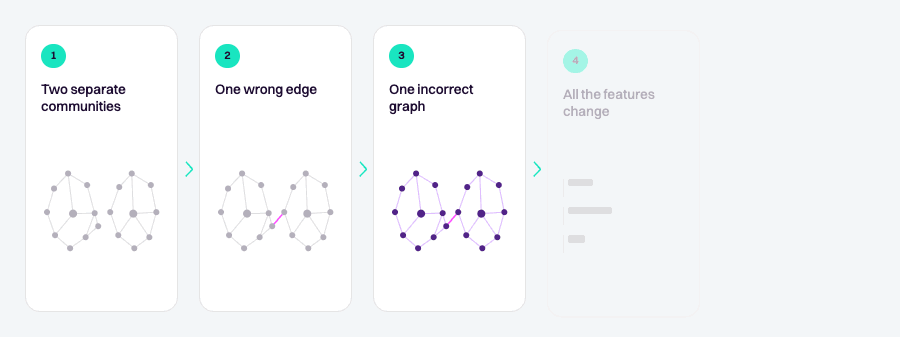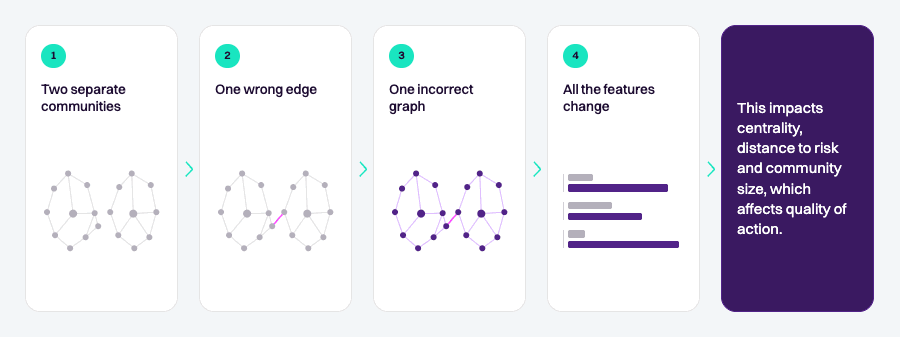
By the same token, a graph can only be successful if the nodes (entities) that inform the edges are true and contextually relevant to the use case.
Trusted meaningful entities: The foundation of trusted AI
As organizations develop AI strategies, discussions normally begin with models. Which model should we use? Which agent framework should we deploy? How should we orchestrate reasoning and workflows?
Those questions only deliver utility when we know who and what our data refers to. When that answer is unclear, a model will struggle to make up the difference.
So, Entity Resolution provides the foundation upon which identity and relationship-based analytics, AI, investigation, and decision-making can operate with confidence. It creates a stable understanding of people, organizations, places, assets, and relationships before those entities are passed to downstream systems.
It brings more accurate measurement and reporting to analytics, richer networks and stronger evidence to investigations, better-grounded reasoning and more reliable outputs to AI, and, for decision-makers, greater confidence that the information behind a decision reflects reality.
As AI takes on more of the decision-making itself, getting that foundation right stops being optional. Trusted decisions start with trusted Entities.
Watch the webinar Before AI, Before Analytics: Get the Entity Right, for a deeper dive into why entities sit at the foundation of trusted analytics, AI, and decisioning.